

Introduction
Businesses drown in repetitive digital work, from copying data from forms into CRMs and checking inventory levels to emailing suppliers and reviewing support tickets before routing them to the right team. None of these tasks is particularly difficult, but together, they consume a significant amount of time.
Droven.io AI Automation Tools are designed to remove that friction by combining traditional workflow automation with AI-driven decision-making, so a pipeline doesn’t just move data; it can also read, interpret, and act on it. This guide breaks down how that works, how it compares to alternatives, and what a real deployment looks like from first setup to production.
What Droven.io Actually Is
Droven.io sits in a category people now call “AI-driven adaptive orchestration.” That’s a mouthful, so here’s the plain version: it’s a platform that connects your apps and data sources, then lets you insert AI models into the workflow to make decisions a simple if/then rule couldn’t handle.
A traditional automation tool can move a file from folder A to folder B when a condition is met. An AI-driven platform can read the contents of that file, decide what kind of document it is, extract the relevant fields, and route it differently depending on what it finds. Droven.io is built around that second capability.

Traditional Workflow Automation vs. AI-Driven Adaptive Orchestration
The difference matters because it changes what kind of problems you can automate.
| Capability | Traditional Automation (e.g., basic Zapier zaps) | AI-Driven Adaptive Orchestration (Droven.io) |
| Trigger logic | Fixed rules, exact matches | Fixed rules plus semantic/contextual matching |
| Data handling | Structured fields only | Structured and unstructured (text, PDFs, emails) |
| Decision-making | Predefined branches | Model-generated branching based on content |
| Error tolerance | Fails on unexpected input | Can retry, reroute, or flag for human review |
| Best fit | Repetitive, predictable tasks | Tasks that involve judgment or interpretation |
Traditional tools still have their place. If a task never varies, you don’t need a model deciding anything; you need a rule that runs the same way every time, cheaply and predictably. Droven.io earns its cost when the input varies enough that rules alone start to break.
Droven.io AI Automation Tools: Core Capabilities and Integrations

Trigger-Action Logic, JSON Data Mapping, and API Endpoints
Every Droven.io pipeline starts with a trigger: a webhook call, a scheduled interval, a new database row, an incoming email. From there, the platform maps incoming data, usually JSON, into the fields each downstream step needs.
This mapping step is where a lot of automation platforms quietly fail. Real-world data is messy. A webhook payload from one system might nest a customer’s email three levels deep in the JSON structure; another might put it at the top level. Droven.io’s mapping layer handles this kind of inconsistency through configurable transformation rules, so you’re not rebuilding your pipeline every time an upstream system changes its schema slightly.
API endpoints in Droven.io follow standard REST conventions, which matters for two practical reasons. First, your engineering team can test and debug pipelines with tools they already know, like Postman or curl. Second, it means Droven.io plays reasonably well with internal tools that weren’t built with no-code platforms in mind.
Native Integrations with CRMs, Databases, and LLM Providers
Droven.io ships with pre-built connectors for the tools most businesses already run: CRMs like Salesforce and HubSpot, databases such as PostgreSQL and MongoDB, and a handful of LLM providers for the AI-generation steps.
The LLM connector piece deserves attention. Rather than locking you into one model provider, Droven.io generally lets you swap models per workflow step. That flexibility matters for cost control; you might use a smaller, cheaper model for simple classification tasks and reserve a more capable model for steps that need nuanced reasoning, like drafting a customer response.
Original Benchmark Performance Analysis
Methodology: Evaluating Speed, Concurrency, and Token Usage
When you’re comparing automation platforms, three metrics tell you most of what you need to know:
- Latency: how long a single execution takes, end-to-end
- Concurrency handling: how the platform behaves when many executions fire at once (a product launch, a marketing email blast, a Black Friday spike)
- Token consumption: how efficiently a workflow uses AI model calls, since this is often the highest recurring cost
A reasonable way to test any platform under these conditions: run a workload that mimics a real spike, like a burst of webhook requests arriving in a short window, and track failure rate, average response time, and cost per completed transaction. Whether you’re evaluating Droven.io, Zapier AI, or Make, you should ask each vendor for their own concurrency benchmarks, or run a limited pilot yourself before committing.
Comparative Performance: What to Look For
| Factor | Droven.io | Zapier AI | Make | Custom Python/RAG stack |
| Setup speed | Fast, visual builder | Fast, visual builder | Moderate, visual builder | Slow, requires development |
| Handling unstructured data | Strong, built for it | Limited | Moderate | Strong, but you build it yourself |
| Cost predictability | Usage-based, model-dependent | Usage-based | Usage-based | Fixed infra cost, variable API cost |
| Customization ceiling | High within the platform | Moderate | Moderate-high | Unlimited |
| Maintenance burden | Low | Low | Low-moderate | High |
The honest takeaway: no-code AI platforms like Droven.io win on speed to deploy and on handling messy, real-world data without custom engineering. Custom-built stacks win on ceiling; there’s no limit to what you can build if you have the engineering time. Most businesses don’t have unlimited engineering time, which is exactly why platforms like this exist.
Step-by-Step Architectural Implementation Framework
Building a production-grade pipeline isn’t just dragging a few nodes onto a canvas. Here’s a framework that holds up under real load.

Step 1: Mapping Process Bottlenecks and Data Schemas
Before touching the platform, map the process on paper. Where does data enter the system? What format is it in? Where does a human currently make a judgment call, and could a model replace or assist with that judgment? When automation extends into physical systems, teams can also consider how automation and robotics fit into the broader process. Write down every data schema you’ll touch: the webhook payload, the CRM object structure, the database table.
Skipping this step is the single most common reason automation projects stall. Teams start building before they understand their own data, then spend weeks patching mapping errors that a day of planning would have caught.
Step 2: Configuring Triggers, Condition Branches, and AI Transformations
With the map in hand, build the pipeline in layers:
- Set up the trigger and confirm it fires reliably on test data.
- Add condition branches for the cases you already know about the 80% of traffic that’s predictable.
- Insert an AI transformation step only where a rule genuinely can’t handle the variation: classifying free-text support tickets, extracting fields from unstructured documents, drafting a response that needs to sound human.
Resist the urge to route everything through an AI step by default. Every model call adds latency and cost. Reserve it for the parts of the workflow that actually need interpretation.
Step 3: Implementing Deterministic Validation and Error-Handling Loops
This is the step teams skip, and it’s the one that determines whether a pipeline survives contact with production traffic.
AI model outputs vary; the same input can produce slightly different results across runs. That’s fine for a first draft of marketing copy. It’s not fine for a step that writes directly to a financial database. Add a validation layer between every AI-generated output and any system of record: a schema check, a business-rule check, or, in high-stakes cases, a human-in-the-loop review gate before the action commits.
Pair this with retry logic that uses exponential backoff, waiting progressively longer between retry attempts so a temporary API hiccup doesn’t cascade into a flood of failed requests hitting a struggling service even harder.
Case Study: Operations Overhaul
To make this concrete, here’s how a mid-market e-commerce company might approach automating post-purchase support and inventory reconciliation with a Droven. io-style pipeline.
Baseline Metrics Before Implementation
Before automation, this kind of company typically handles post-purchase questions “where’s my order,” “can I return this,” “is this back in stock” manually. Support agents read each ticket, check an inventory system, and reply by hand. Resolution times commonly run into many minutes per ticket, and escalation rates to senior staff sit well above what the team would like, because agents lack quick access to real-time inventory data.
System Setup, Node Configuration, and Database Synchronization
A typical build looks like this:
- A trigger fires on every new support ticket.
- An AI classification step reads the ticket text and sorts it into categories: shipping status, return request, stock inquiry, or “needs a human.”
- For shipping and stock questions, the pipeline queries the inventory and order-management databases directly, then drafts a response using the retrieved data through a retrieval-augmented generation (RAG) approach. This grounds the model’s answer in real, current records rather than guesses.
- A validation step checks the drafted response against the source data before it sends, catching cases where the model might have misread a field.
- Anything flagged “needs a human” routes to a live agent with the ticket already categorized and the relevant data pre-loaded.
Post-Deployment Performance and ROI Considerations
Companies that automate this kind of workflow well typically see resolution times for routine tickets drop from minutes to seconds, since the AI-and-database combination answers instantly instead of waiting for an agent to look things up. Escalation rates also tend to fall, although the exact numbers depend heavily on ticket variety and how well you tune the validation layer.
The real ROI calculation isn’t just about time saved; it’s about what your support team does with that recovered time. Teams that redirect freed-up hours toward complex cases or proactive outreach see a better return than teams that simply reduce headcount.
Security, Compliance, and Risk Mitigation
Managing API Key Security and Data Encryption Standards
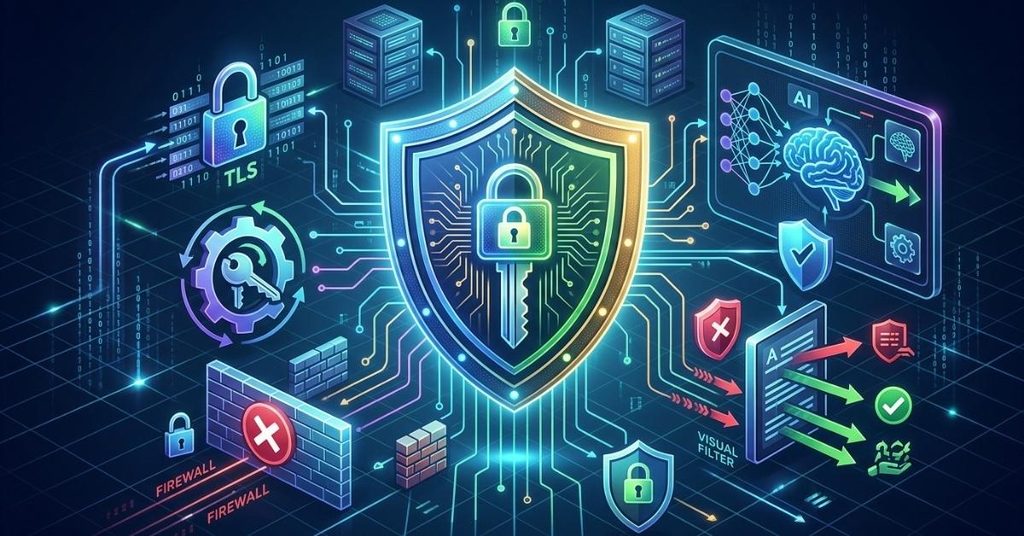
Every integration point is a potential exposure point. A few practices that matter regardless of which platform you use:
- Store API keys in a secrets manager, never in plain workflow configuration.
- Rotate keys on a schedule, and immediately after any team member with access leaves.
- Confirm that the system encrypts data both in transit (TLS) and at rest, especially when handling customer PII or financial data.
- Scope API keys to the minimum permissions each integration actually needs; a workflow that only reads inventory data shouldn’t hold write access to your CRM.
Guardrails Against LLM Hallucinations and Prompt Injection Vulnerabilities
Two risks are specific to AI-driven pipelines that traditional automation doesn’t face. AI automation tools can introduce additional risks when models make decisions or process untrusted inputs.
Hallucination: A model can confidently generate incorrect information. For high-risk workflows, validate outputs before they trigger consequential actions.
Prompt injection happens when malicious text embedded in incoming data (a support ticket, an email, a document) tries to manipulate the model into ignoring its instructions. Defend against this by treating all incoming content as untrusted data, not instructions; keep your system prompts separate from user-supplied content; and add a filtering step that checks AI outputs for signs the model deviated from its intended task before any action executes.
The Fail-Safe Automation Framework
A useful mental model for building resilient pipelines breaks error-handling into four tiers:

Tier 1: Input validation. Reject or flag malformed data before it enters the pipeline at all.
Tier 2: Retry with backoff. The system handles temporary API and infrastructure failures through controlled retries.
Tier 3: Deterministic checks on AI output. AI results are verified before downstream actions.
Tier 4: Human-in-the-loop escalation. Anything that fails Tier 3, or that crosses a risk threshold you define (a large financial transaction, a legal commitment), routes to a person instead of executing automatically.
Building all four tiers takes more setup time than skipping straight to “trigger, AI step, action.” It’s also the difference between a pipeline that handles a bad week gracefully and one that quietly corrupts data until someone notices.
FAQ
Is Droven.io a replacement for Zapier or Make?
Not exactly. It overlaps with both but leans harder into AI-driven decision-making and unstructured data handling. If your workflows are simple and predictable, a lighter tool may cost less and do the job fine. If your workflows involve judgment calls on messy data, Droven.io’s approach is more purpose-built.
Do I need to know how to code to use Droven.io?
No, for most workflows. The visual builder covers triggers, conditions, and standard integrations without code. Complex custom logic or unusual API integrations may still benefit from a developer’s involvement.
How does Droven.io handle rate limits from connected APIs?
Well-built pipelines handle this with retry logic and exponential backoff, as described in the Fail-Safe Framework above. Confirm that any platform you choose supports configurable retry behavior; it’s not universal.
What happens when an AI model produces an incorrect answer?
Validation should catch an incorrect AI answer before it triggers a consequential action. Teams can also route high-risk cases to a human for review.
Do You Need Retrieval-Augmented Generation (RAG) for Every Use Case?
No. RAG adds value when you need to ground responses in current, specific data, such as order status, inventory levels, and account details. For tasks that don’t require real-time or proprietary data, a simpler model call without retrieval is faster and cheaper.
How should I evaluate ROI before committing to a platform?
Calculate cost per completed transaction, not just subscription price. Factor in token/API costs, setup time, and critically, what your team does with the hours saved. A tool that saves time but sits unused doesn’t generate ROI.
Conclusion
AI-driven automation platforms like Droven.io solve a real problem: rules-based tools break down the moment data gets messy or a task requires judgment. The tradeoff is that AI steps introduce non-determinism, and non-determinism without validation is a liability, not a feature.
The teams that get the most value build carefully. They map their process before they build it. They reserve AI steps for the parts of the workflow that actually need interpretation. The system validates every AI output before entering it into the system of record. And they treat security API key management, injection defenses, encryption as part of the build, not an afterthought.
For teams evaluating Droven.io AI Automation Tools, the best approach is to start small. Pick one workflow with clear, measurable pain: a support queue, a data-entry bottleneck, or an inventory check. Build it with all four tiers of the Fail-Safe Framework in place. Get that one right, then scale out from there.

I’m Qasim Ali, the Founder and Technology Writer at TechRised, with 10+ years of experience and a strong academic background in technology and emerging digital innovations. My expertise spans Generative AI, AI Automation, Robotics, Computer Vision, and Machine Learning. I specialize in researching emerging technologies, analyzing industry trends, and transforming complex technical concepts into clear, practical, and reliable insights. Through TechRised, I share research-driven content to help readers understand the latest advancements in AI and the technologies shaping the future.